About René Schwietzke
- Master of Computer Science (Dipl.-Inf.)
- Programming since 1987
- Java since Java
1.0.2, 1996 - QA and Testing since 1998
- Performance Tester since 1999
- Co-Founder of

-
@reneschwietzke@foojay.social -
@reneschwietzke.bsky.social - Blog reneschwietzke.de
-
@ReneSchwietzke

About
- Founded 2004
- Headquarters in Jena, Germany
- Subsidiary in Cambridge, MA, USA
- Specialized in Software Testing and Quality Assurance
- Over 150 performance test projects every year
- World-wide customer base including APAC and South America
- Performance Test Tool
 , Java-based, APL 2.0
- SaaS Performance Testing Offering

License
I care and share
c b
This presentation is licensed under
Creative Commons Attribution 4.0 International License
#1BRC - Introduction
What is 1BRC and why the fuss?

The Origin
A busy January 2024 for Java Devs
- Gunnar Morling got bored during the holidays
- His wife suggested doing something nice and fun
- So he asked the community the #1brc question
... write a Java program for retrieving temperature measurement values from a text file and calculate the min, mean, and max temperatures per weather station.
... one caveat, the file has 1,000,000,000 rows!

Data
Input
Zagreb;19.7
Havana;36.2
Mexicali;27.3
Marseille;15.4
Banjul;24.2
Canberra;0.8
Mandalay;19.3
Bridgetown;29.6
Chihuahua;10.9
Honiara;35.3
Gangtok;-1.7
Houston;32.4
Zürich;13.8
Kolkata;20.6
Tripoli;8.9
Karachi;28.3
Zagreb;13.2
Palm Springs;20.3
Lhasa;6.2
Sacramento;28.3
Edmonton;5.6
Toluca;14.0
El Paso;24.0
Antsiranana;24.9
Tromsø;-3.9
Output
# This is TreeMap::toString
# Data shown here is formatted for screen
{
   Abha=5.0/18.0/27.4, Abidjan=15.7/26.0/34.1,
   Abéché=12.1/29.4/35.6, Accra=14.7/26.4/33.1,
   Addis Ababa=2.1/16.0/24.3, Adelaide=4.1/17.3/29.7,
   ...
   Willemstad=-7.9,28.2,57.7, Winnipeg=-28.1,3.0,39.4,
   Wrocław=-27.5,9.6,50.2, Xi'an=-22.5,14.0,49.1,
   Yakutsk=-42.2,-8.8,26.4, Yangon=-2.6,27.6,59.0,
   Yaoundé=-10.1,23.6,58.3, Yellowknife=-38.4,-4.0,40.0,
   Yerevan=-18.4,12.4,49.6, Yinchuan=-25.4,9.5,42.0,
   Zagreb=-25.3,10.6,48.4, Zanzibar City=-5.0,26.1,61.2,
   Zürich=-20.9,9.4,43.5, Ürümqi=-26.8,7.4,43.7,
   İzmir=-15.8,18.0,50.1
}
- 1 billion rows
- Size 13.8 GB
Rules
Fewer Questions, More Doing
- Java Only
- JDKs via SDKMAN only, any version!
- Any CLI parameters permitted
- No external dependencies
- Results measured on bare metal
- File in RAM (RAMdisk or file cache)
- No preprocessing of the data permitted
- Five measurements, middle three averaged
- Max 10k stations
- Initial version 413 stations
- Only valid data in the file, UTF-8
- Line ending is always
\n - City names max 100 bytes (unicode)
- Temperatures -99.9 to 99.9 (e.g. 5.0, 0.0)
- IEEE 754 rounding-direction "roundTowardPositive"
The Results
What do you think? Guess some numbers.
| Test | Cores | Time (s) | % |
|---|---|---|---|
| Baseline | 1 | 125.1 s | 100.0% |
| Thomas Wuerthinger | 1 | 7.4 s | 5.9% |
| Previous 20% Goal / Achieved | 1 | 25.0 s / 19.5 s | 20.0% / 15.6% |
| Baseline | 8 | 77.3 s | 61.8% |
| Thomas Wuerthinger | 8 | 1.6 s | 1.2% |
| Thomas Wuerthinger | 16 | 0.85 s | 0.7% |
| Today's 20% Goal | 8 | 15.5 s | 20.0% |
Motivation and Rules
Just to Make Things Easier
Why?
- It is about getting there and learning from mistakes
- We will do naive things which for 80% are obviously stupid.
- Use some metrics to see culprits
- Be amazed when obvious things fail
- Hear about behind-the-scenes magic
Updated Rules
- 1SBF: One Simple Benchmark Framework
- Limit measurements to code in question
- Exclude startup and shutdown of JVM
- New instance of the test class per round
- Updated output format
Berlin=23615/-0.412/6.310/15.243- SHA-512 of result to discover differences
Limitations
- Talk time is not enough for all details
- 80% don't require all tricks
- No Über-Code today!
- Only things you can reuse too!
- Real world gains vary a lot
- No AI-Assisted optimizations today!
- No Unsafe
- No Vector API
- No Graal
- No Bit-Magic
- No Branchless Code
- No Memory-Mapped Files
- No JNI/FFI
Goal: All code is still easily understandable.
private static record Measurement(String station, double value) {
    private Measurement(String[] parts) {
        this(parts[0], Double.parseDouble(parts[1]));
    }
}

Collector<Measurement, MeasurementAggregator, ResultRow> collector = Collector.of(
        MeasurementAggregator::new,
        (a, m) -> {
            a.min = Math.min(a.min, m.value);
            a.max = Math.max(a.max, m.value);
            a.sum += m.value;
            a.count++;
        },
        (agg1, agg2) -> {
            var res = new MeasurementAggregator();
            res.min = Math.min(agg1.min, agg2.min);
            res.max = Math.max(agg1.max, agg2.max);
            res.sum = agg1.sum + agg2.sum;
            res.count = agg1.count + agg2.count;

            return res;
        },
        agg -> {
            return new ResultRow(agg.count, agg.sum, agg.min, agg.max);
        });

Map<String, ResultRow> measurements =
        Files.lines(Paths.get(fileName))
        .map(l -> l.split(";"))
        .map(a -> new Measurement(a))
        .collect(Collectors.groupingBy(m -> m.station(), collector));

return new TreeMap<>(measurements).toString();
The Flow Visualized
The basic concept of the 1BRC pipeline

The Results
| Test | C | Time (s) | % |
|---|---|---|---|
| BRC001_Baseline | 1 | 125.1 | 100.0 |
| BRC004_...w/o Collector | 1 | 105.6 | 84.4 |
| BRC003_BaselineFileAndSplit | 1 | 82.5 | 65.9 |
| BRC002_BaselineFileOnly | 1 | 44.7 | 35.7 |
Parallel Architecture
Where it can be parallelized
- Using standard stream parallelization features
.parallel()Collectors.groupingByConcurrent- Different points to fork the stream
Map<String, ResultRow> measurements =
        Files.lines(Paths.get(fileName)).parallel()
        .map(l -> l.split(";"))
        .map(a -> new Measurement(a))
        .collect(
                Collectors.groupingBy(m -> m.station(), collector));

Map<String, ResultRow> measurements =
        Files.lines(Paths.get(fileName))
        .map(l -> l.split(";"))
        .map(a -> new Measurement(a)).parallel()
        .collect(
                Collectors.groupingBy(m -> m.station(), collector));

Map<String, ResultRow> measurements =
        Files.lines(Paths.get(fileName)).parallel()
        .map(l -> l.split(";")).parallel()
        .map(a -> new Measurement(a)).parallel()
        .collect(
                Collectors.groupingBy(m -> m.station(), collector));

...
        .collect(
                Collectors.groupingByConcurrent(m -> m.station(), collector));

Map<String, ResultRow> measurements =
        Files.lines(Paths.get(fileName)).parallel()
        .map(l -> new Measurement(l.split(";")))
        .collect(
                Collectors.groupingByConcurrent(m -> m.station(), collector));
Results
| Test | C | Time | % |
|---|---|---|---|
| BRC001_Baseline | 1 | 125.1 | 100.0 |
| BRC002_BaselineFileOnly | 1 | 44.7 | 35.7 |
| BRC003_BaselineFileAndSplit | 1 | 82.5 | 65.9 |
| BRC004_...w/o Collector | 1 | 105.6 | 84.4 |
| BRC010_ParallelAfterRead | 8 | 77.3 | 61.8 |
| BRC011_ParallelAfterMapping | 8 | 77.2 | 61.7 |
| BRC012_ParallelBoth | 8 | 77.3 | 61.8 |
| BRC013_ParallelAll | 8 | 77.2 | 61.7 |
| BRC014_ParallelGrouping | 8 | 79.1 | 63.2 |
| BRC015_Parallel_NoCollector | 8 | 74.5 | 59.6 |
| BRC016_Compact | 8 | 79.0 | 63.1 |
// BRC014_ParallelGrouping
Map<String, ResultRow> measurements =
        Files.lines(Paths.get(fileName)).parallel()
        .map(l -> l.split(";")).parallel()
        .map(a -> new Measurement(a))
        .collect(
                Collectors.groupingByConcurrent(
                    m -> m.station(), collector));


// BRC016_Compact
Map<String, ResultRow> measurements =
    Files.lines(Paths.get(fileName)).parallel()
    .map(l -> new Measurement(l.split(";")))
    .collect(
            Collectors.groupingByConcurrent(
                m -> m.station(), collector));
parallel()more than once is not doing anything. It is not working as one might imagine.
@Override
public String run(final String fileName) throws IOException {
    // our storage
    final Map<String, Temperatures> cities = new HashMap<>();

    // open the file
    try (var reader = Files.newBufferedReader(Paths.get(fileName))) {
        String line;

        // read all lines until end of file
        while ((line = reader.readLine()) != null) {
            // split the line
            final String[] cols = line.split(";");

            // first is the city
            final String city = cols[0];
            // second our double temperature
            final double temperature = Double.parseDouble(cols[1]);

            // get us our measurement record
            var measurement = new Temperatures(temperature);

            // store it, when it exists, merge both measurements otherwise
            cities.merge(city, measurement, (t1, t2) -> t1.merge(t2));
        }
    }

    // ok, we got everything, now we need to order it
    return new TreeMap<String, Temperatures>(cities).toString();
}
The Results
| Test | C | Time | % |
|---|---|---|---|
| BRC001_Baseline | 1 | 125.1 | 100.0 |
| BRC002_BaselineFileOnly | 1 | 44.7 | 35.7 |
| BRC003_BaselineFileAndSplit | 1 | 82.5 | 65.9 |
| BRC004_...w/o Collector | 1 | 105.6 | 84.4 |
| BRC010_ParallelAfterRead | 8 | 77.3 | 61.8 |
| BRC011_ParallelAfterMapping | 8 | 77.2 | 61.7 |
| BRC012_ParallelBoth | 8 | 77.3 | 61.8 |
| BRC013_ParallelAll | 8 | 77.2 | 61.7 |
| BRC014_ParallelGrouping | 8 | 79.1 | 63.2 |
| BRC015_Parallel_NoCollector | 8 | 74.5 | 59.6 |
| BRC016_Compact | 8 | 79.0 | 63.1 |
| BRC020_NoStream | 1 | 127.6 | 102.1 |
| BRC021_NoStreamFileOnly | 1 | 41.7 | 33.3 |
The Flow
The updated flow w/o streams

Take a Programming Book
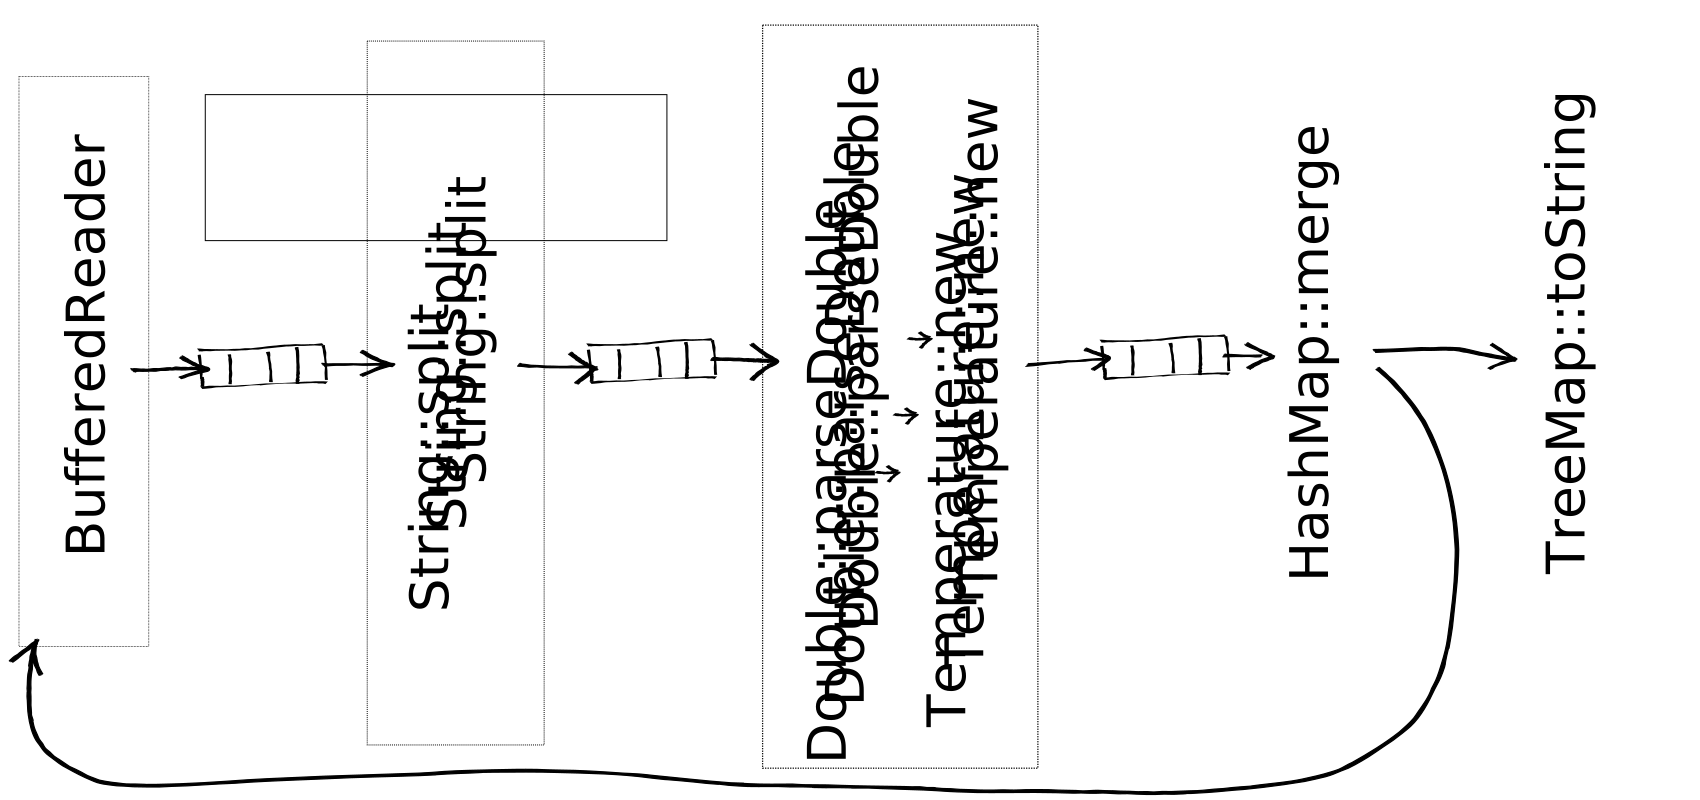
Producer-Consumer
- Do the first thing you learned as a programmer
- You have one producer:
FileReader - You have chained consumers: Split, Parse, Create Data
- You have one specialized consumer, a reducer:
Map::merge - Communicate between them using queues
- Signal the end using a poison pill
Producer-Consumer
Brute force beginner parallelism
public String run(final String fileName)
{
    // let's do a raw and basic old-school implementation without
    // most modern Java help
    BlockingQueue<String> splittingQueueInput = new LinkedBlockingDeque<>(100);
    BlockingQueue<String[]> measureQueueInput = new LinkedBlockingDeque<>(100);
    BlockingQueue<Temperatures> mappingQueueInput = new LinkedBlockingDeque<>(100);

    int consumerCount = Math.max(1, (this.getThreadCount() - 2) / 2);

    var readerThread = new ReaderThread(Paths.get(fileName), splittingQueueInput, consumerCount);
    readerThread.start();

    for (int i = 0; i < consumerCount; i++)
    {
        var sThread = new SplittingThread(splittingQueueInput, measureQueueInput);
        sThread.start();

        var mThread = new MeasurementThread(measureQueueInput, mappingQueueInput);
        mThread.start();
    }

    var mapperThread = new MapperThread(mappingQueueInput, consumerCount);
    mapperThread.start();

    // wait till done
    try
    {
        mapperThread.join();
    }
    catch (InterruptedException e)
    {
        throw new RuntimeException(e);
    }

    // get our result
    var cities = mapperThread.getCities();

    // ok, we got everything, now we need to order it
    return new TreeMap<String, Temperatures>(cities).toString();
}
Variations on the theme
Let's try some variations on the theme
BRC025_1_N_N_1: 1 producer, N splitters, N measurement, 1 aggregatorBRC026_1_N_N_1_LargeBuffers: BRC025_1_N_N_1 with buffers of 100,000 instead of 100BRC027_1_N_N_1_Batches: BRC026_1_N_N_1_LargeBuffers but batches of 5,000 entriesBRC028_1_N_1: 1 producer, N split + measurement, 1 aggregator
Results
| Test | C | Time | % |
|---|---|---|---|
| BRC001_Baseline | 1 | 125.1 | 100.0 |
| BRC002_BaselineFileOnly | 1 | 44.7 | 35.7 |
| BRC003_BaselineFileAndSplit | 1 | 82.5 | 65.9 |
| BRC004_...w/o Collector | 1 | 105.6 | 84.4 |
| BRC010_ParallelAfterRead | 8 | 77.3 | 61.8 |
| BRC011_ParallelAfterMapping | 8 | 77.2 | 61.7 |
| BRC012_ParallelBoth | 8 | 77.3 | 61.8 |
| BRC013_ParallelAll | 8 | 77.2 | 61.7 |
| BRC014_ParallelGrouping | 8 | 79.1 | 63.2 |
| BRC015_Parallel_NoCollector | 8 | 74.5 | 59.6 |
| BRC016_Compact | 8 | 79.0 | 63.1 |
| BRC020_NoStream | 1 | 127.6 | 102.1 |
| BRC021_NoStreamFileOnly | 1 | 41.7 | 33.3 |
| BRC025_1_N_N_1 | 8 | 659.0 | 530.2 |
| BRC026_1_N_N_1_LargeBuffers | 8 | 498.6 | 401.1 |
| BRC027_1_N_N_1_Batches | 8 | 51.9 | 41.8 |
| BRC028_1_N_1 | 8 | ERROR | - |
Improve Parallelism
Large Tasks for the Consumers
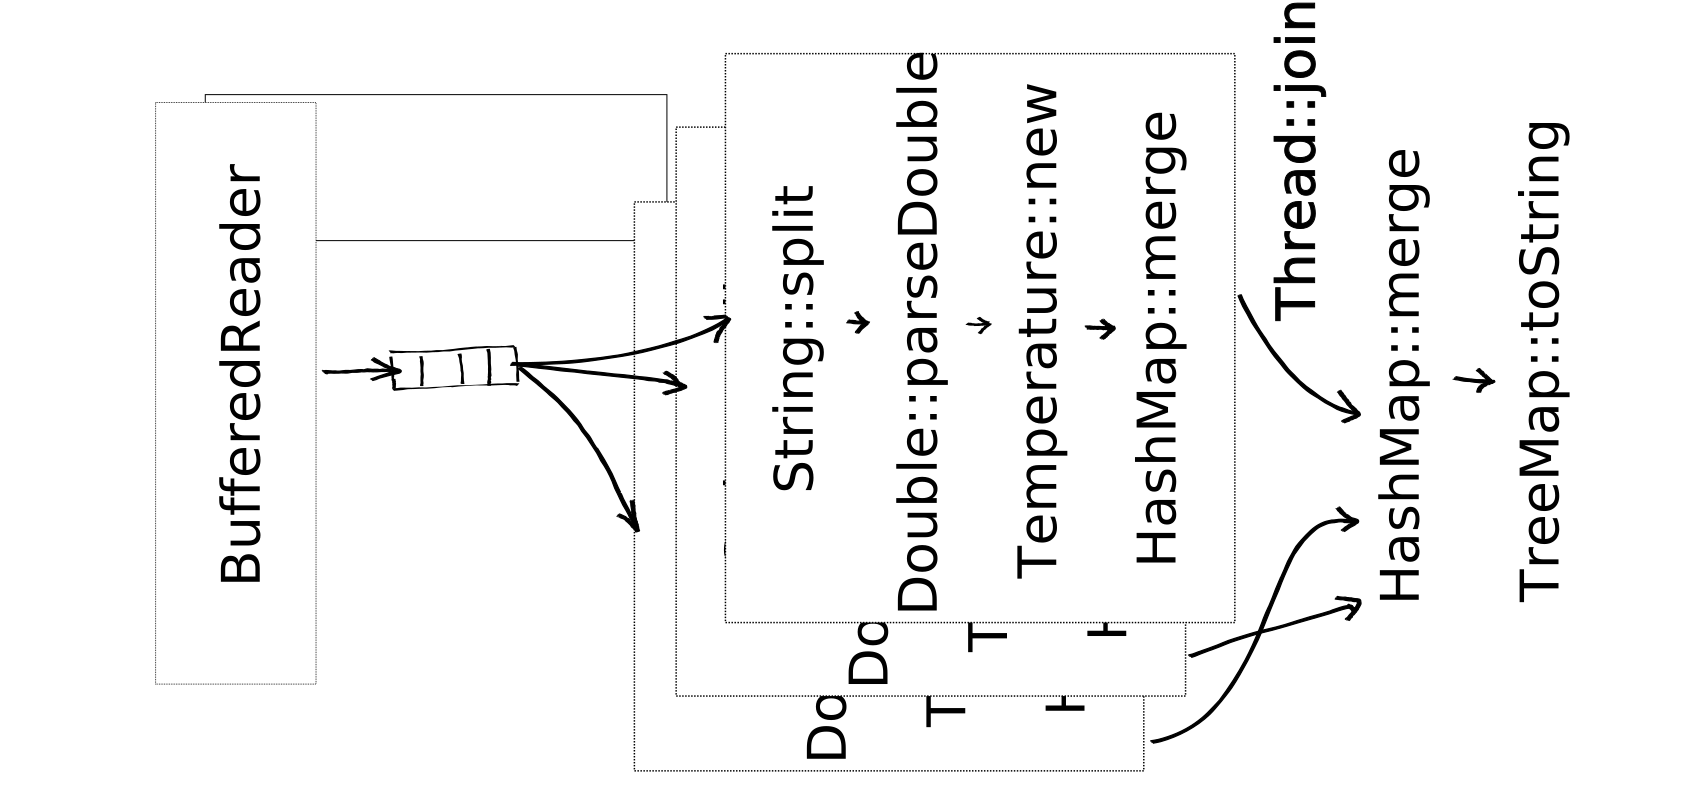
- Go 1:N
- One reader
- N processors for (split, parse, measurement, and local merge)
- Main thread reduces processor results
- Leaves us with one small item queue and N intermediate results
Producer-Map-Reduce-Reduce
One large operation per worker, not a chain of small ones
Variations on the theme
Let's try some variations on the theme
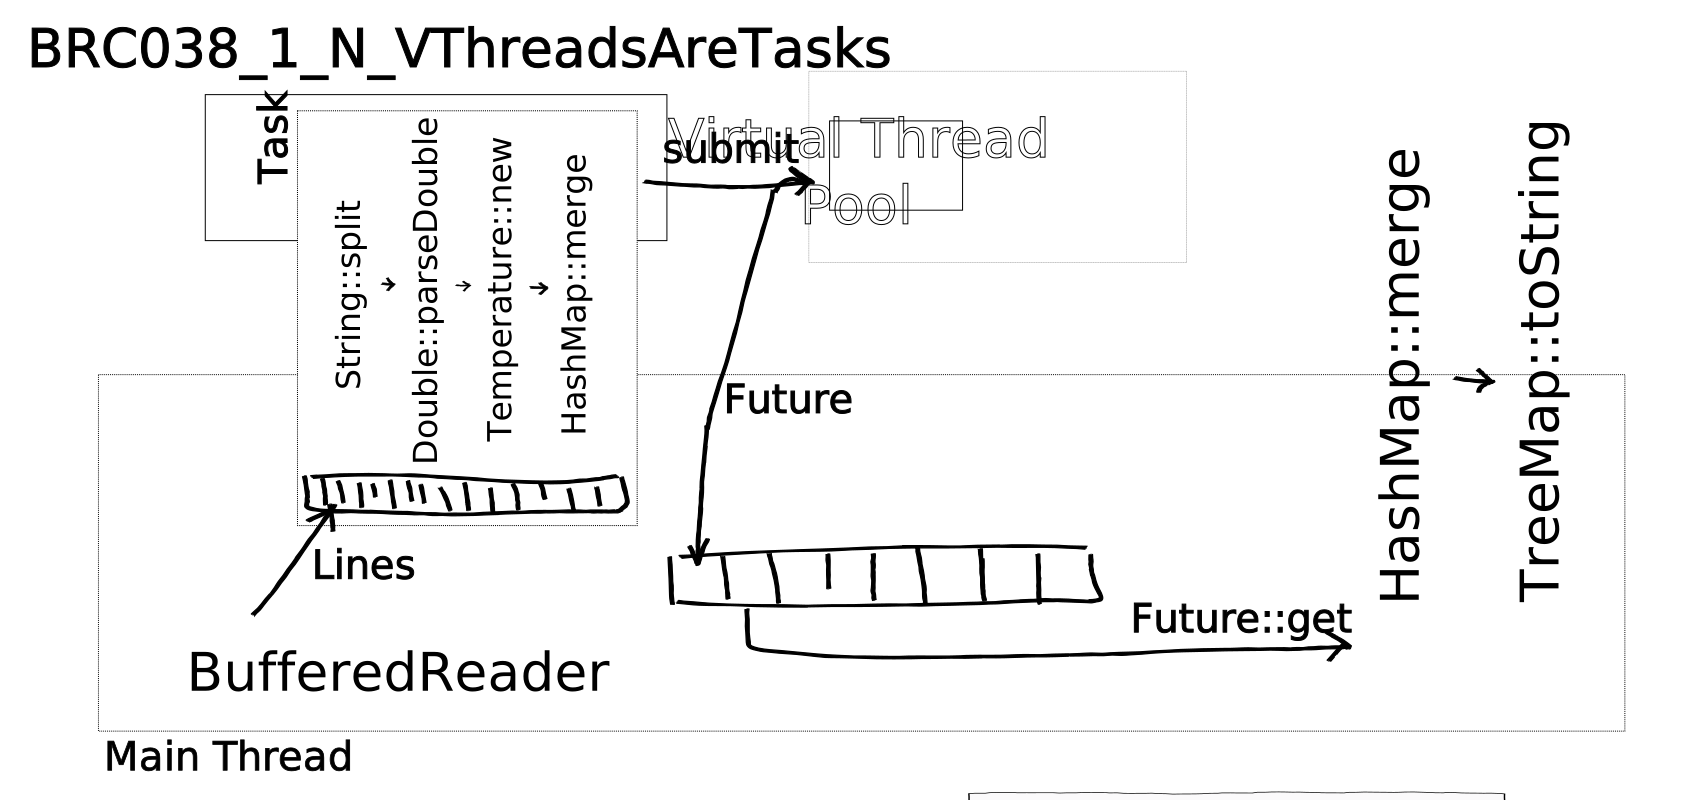
BRC030_1_N: 1:N, main thread reduces the intermediate resultsBRC032_1_N_Batched: BRC030_1_N with batches of 1,000 entriesBRC034_1_N_Virtual: BRC032_1_N_Batched, all virtual threads (manually created)BRC036_1_N_ExecutorPool: BRC032_1_N_Batched with Thread ExecutorPoolBRC038_1_N_VThreadsAreTasks: BRC032_1_N_Batched with batches as tasks into virtual thread executor pool
BRC038_1_N_VThreadsAreTasks
Looks Different
Results
| Test | C | Time | % |
|---|---|---|---|
| BRC001_Baseline | 1 | 125.1 | 100.0 |
| BRC002_BaselineFileOnly | 1 | 44.7 | 35.7 |
| BRC003_BaselineFileAndSplit | 1 | 82.5 | 65.9 |
| BRC004_...w/o Collector | 1 | 105.6 | 84.4 |
| BRC010_ParallelAfterRead | 8 | 77.3 | 61.8 |
| BRC011_ParallelAfterMapping | 8 | 77.2 | 61.7 |
| BRC012_ParallelBoth | 8 | 77.3 | 61.8 |
| BRC013_ParallelAll | 8 | 77.2 | 61.7 |
| BRC014_ParallelGrouping | 8 | 79.1 | 63.2 |
| BRC015_Parallel_NoCollector | 8 | 74.5 | 59.6 |
| BRC016_Compact | 8 | 79.0 | 63.1 |
| BRC020_NoStream | 1 | 127.6 | 102.1 |
| BRC021_NoStreamFileOnly | 1 | 41.7 | 33.3 |
| BRC025_1_N_N_1 | 8 | 659.0 | 530.2 |
| BRC026_1_N_N_1_LargeBuffers | 8 | 498.6 | 401.1 |
| BRC027_1_N_N_1_Batches | 8 | 51.9 | 41.8 |
| BRC028_1_N_1 | 8 | ERROR | - |
| Test | C | Time | % |
|---|---|---|---|
| BRC030_1_N | 8 | 483.5 | 389.0 |
| BRC032_1_N_Batched | 8 | 102.3 | 82.3 |
| BRC034_1_N_Virtual | 8 | 104.6 | 84.2 |
| BRC036_1_N_ExecutorPool | 8 | 48.5 | 39.0 |
| BRC038_1_N_VThreadsAreTasks | 8 | 47.0 | 37.8 |
A Reader is Sequential
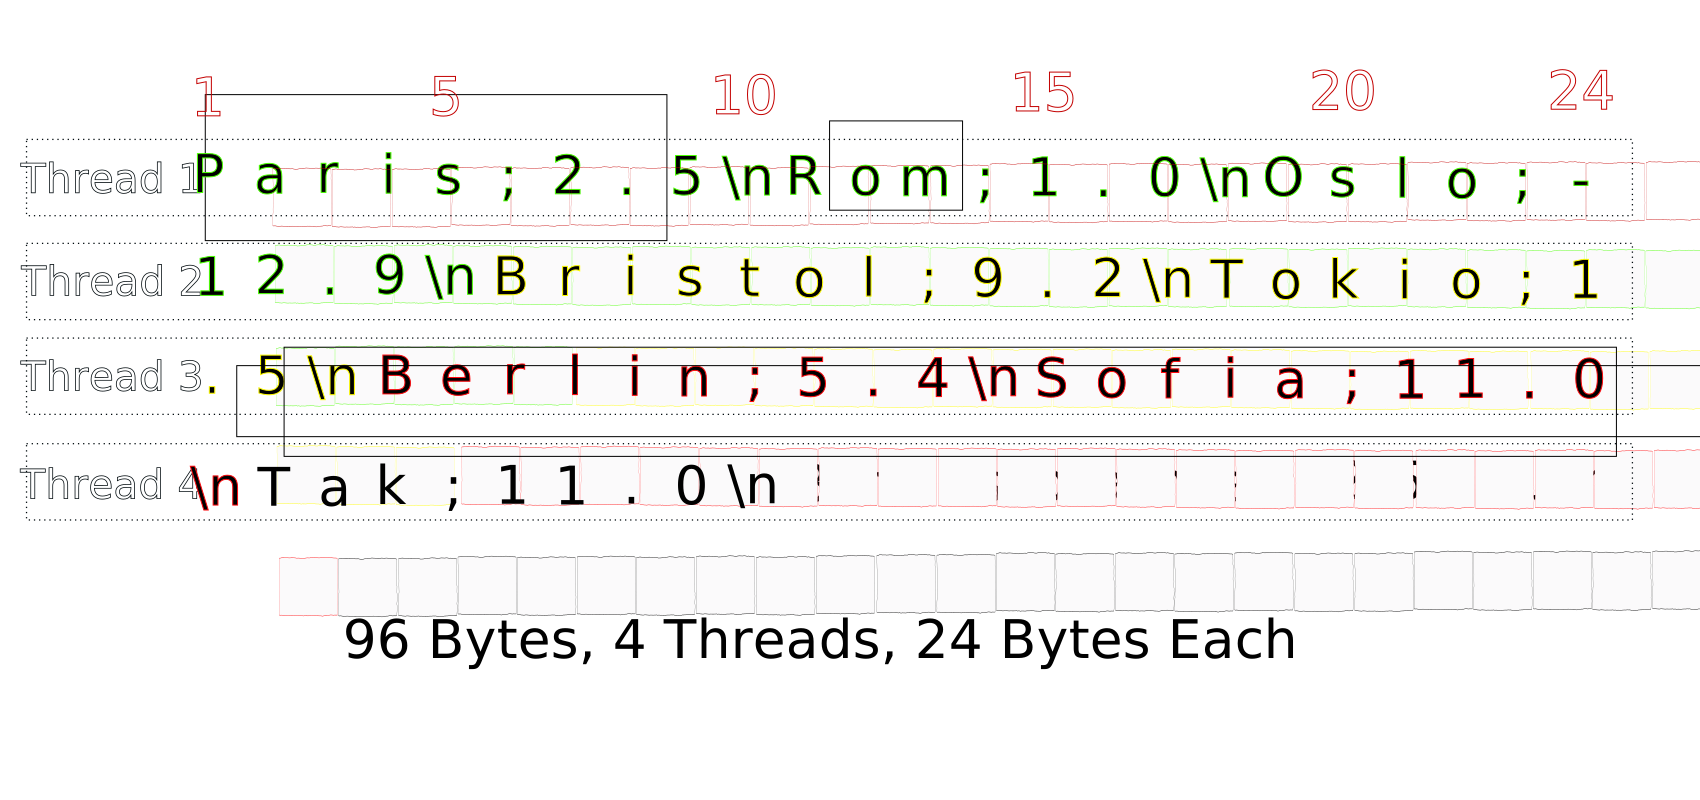
We Cannot Split The Reader Easily
- A
BufferedReaderreadschar charhas unknownbytebacking- Cannot start reading randomly in a file seen as
char - Must jump to position, read bytes, find newline
- Read data until newline as bytes and convert into String
- Important: Each reader must go beyond end position for a complete last line
Positionable Reader
Read data carefully
Results
| Test | C | Time | % |
|---|---|---|---|
| BRC001_Baseline | 1 | 125.1 | 100.0 |
| BRC002_BaselineFileOnly | 1 | 44.7 | 35.7 |
| BRC003_BaselineFileAndSplit | 1 | 82.5 | 65.9 |
| BRC004_...w/o Collector | 1 | 105.6 | 84.4 |
| BRC010_ParallelAfterRead | 8 | 77.3 | 61.8 |
| BRC011_ParallelAfterMapping | 8 | 77.2 | 61.7 |
| BRC012_ParallelBoth | 8 | 77.3 | 61.8 |
| BRC013_ParallelAll | 8 | 77.2 | 61.7 |
| BRC014_ParallelGrouping | 8 | 79.1 | 63.2 |
| BRC015_Parallel_NoCollector | 8 | 74.5 | 59.6 |
| BRC016_Compact | 8 | 79.0 | 63.1 |
| BRC020_NoStream | 1 | 127.6 | 102.1 |
| BRC021_NoStreamFileOnly | 1 | 41.7 | 33.3 |
| BRC025_1_N_N_1 | 8 | 659.0 | 530.2 |
| BRC026_1_N_N_1_LargeBuffers | 8 | 498.6 | 401.1 |
| BRC027_1_N_N_1_Batches | 8 | 51.9 | 41.8 |
| BRC028_1_N_1 | 8 | ERROR | - |
| Test | C | Time | % |
|---|---|---|---|
| BRC032_1_N_Batched | 8 | 102.3 | 82.3 |
| BRC034_1_N_Virtual | 8 | 104.6 | 84.2 |
| BRC036_1_N_ExecutorPool | 8 | 48.5 | 39.0 |
| BRC038_1_N_VThreadsAreTasks | 8 | 47.0 | 37.8 |
| BRC040_N_ConcurrentRead | 8 | 6.4 | 5.1 |
| BRC040_N_ConcurrentRead | 16 | 3.7 | 3.0 |
ForkJoinPool
Using what Java recommends
- ForkJoinPool: Designed for Divide-and-Conquer
- Splits large tasks into smaller ones until they are small enough
- Hides thread management, queues, and "load balancing"
- RecursiveAction: Just performs activities without a direct result
- RecursiveTask: Activity with a result
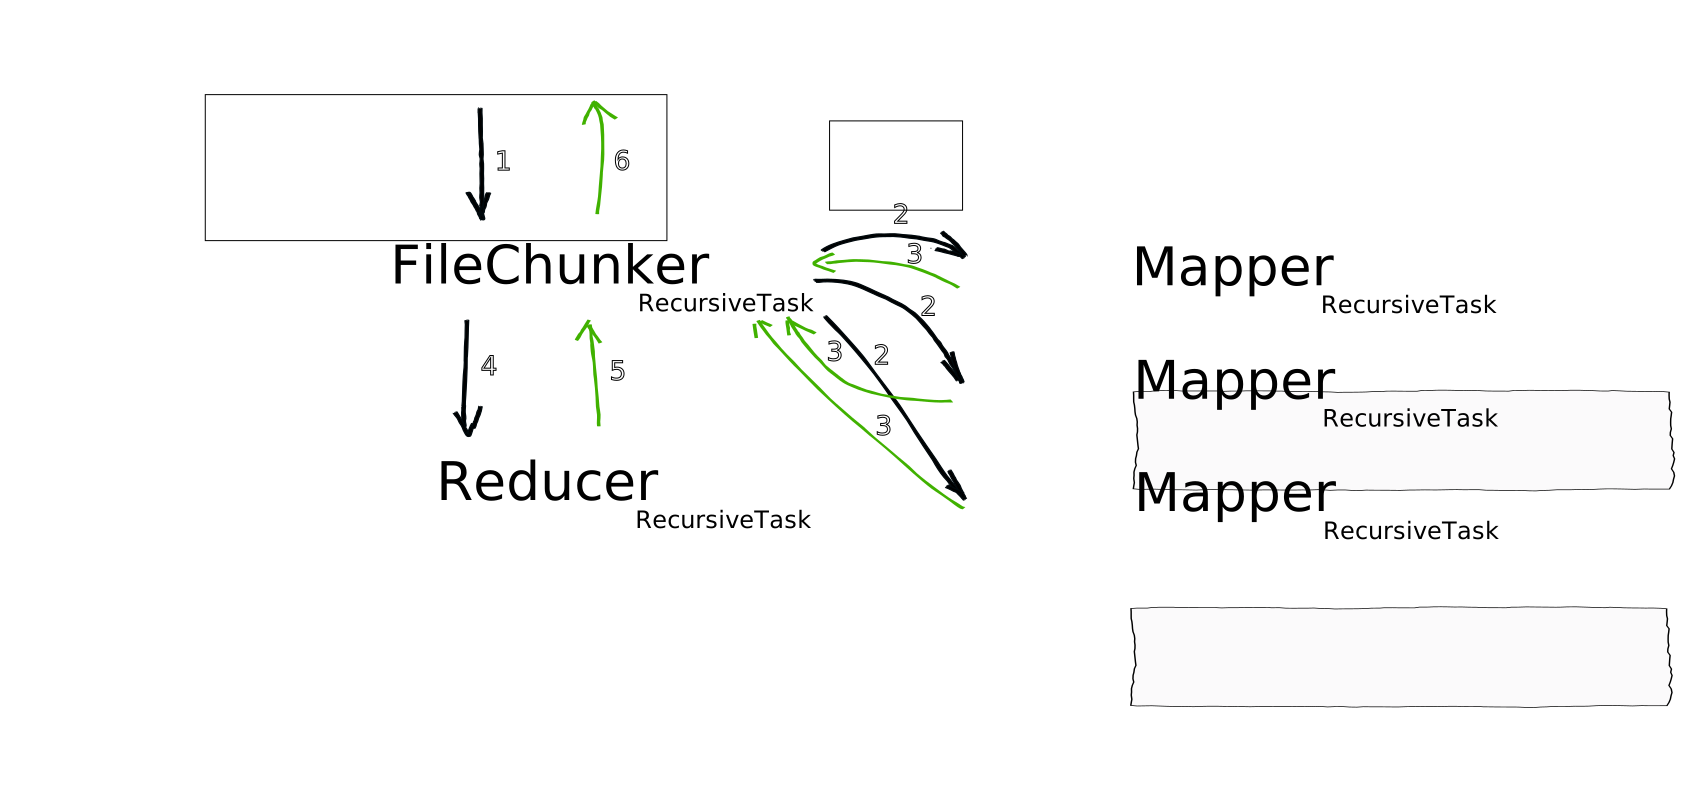
- 1. Determine file size
- 2. Divide file into chunks
- 3. Optionally split up further
- 4. Perform read, split, parse, map, reduce
- 5. Reduce results of 4. further
- 6. Finished
ForkJoinFlow
Divide, Wait, Continue
ForkJoinPool Variations
How to play it
- BRC042_ForkJoinPool: Chunk --> Map --> Reduce
- BRC043_ForkJoinPool_NoReducer: Chunk --> Map, Reduce done by Chunk
- BRC044_ForkJoinPool_SelfSplitting: Mapper --> Mapper --> Mapper... until small enough
- BRC047_VirtualThreads: No ForkJoinPool, just use CPU-count virtual threads
- BRC048_VT_ChunkSize_10MB: Split in 10MB chunks, do everything in virtual threads per task
Results
| Test | C | Time | % |
|---|---|---|---|
| BRC001_Baseline | 1 | 125.1 | 100.0 |
| BRC002_BaselineFileOnly | 1 | 44.7 | 35.7 |
| BRC003_BaselineFileAndSplit | 1 | 82.5 | 65.9 |
| BRC004_...w/o Collector | 1 | 105.6 | 84.4 |
| BRC010_ParallelAfterRead | 8 | 77.3 | 61.8 |
| BRC011_ParallelAfterMapping | 8 | 77.2 | 61.7 |
| BRC012_ParallelBoth | 8 | 77.3 | 61.8 |
| BRC013_ParallelAll | 8 | 77.2 | 61.7 |
| BRC014_ParallelGrouping | 8 | 79.1 | 63.2 |
| BRC015_Parallel_NoCollector | 8 | 74.5 | 59.6 |
| BRC016_Compact | 8 | 79.0 | 63.1 |
| BRC020_NoStream | 1 | 127.6 | 102.1 |
| BRC021_NoStreamFileOnly | 1 | 41.7 | 33.3 |
| BRC025_1_N_N_1 | 8 | 659.0 | 530.2 |
| BRC026_1_N_N_1_LargeBuffers | 8 | 498.6 | 401.1 |
| BRC027_1_N_N_1_Batches | 8 | 51.9 | 41.8 |
| BRC028_1_N_1 | 8 | ERROR | - |
| Test | C | Time | % |
|---|---|---|---|
| BRC032_1_N_Batched | 8 | 102.3 | 82.3 |
| BRC034_1_N_Virtual | 8 | 104.6 | 84.2 |
| BRC036_1_N_ExecutorPool | 8 | 48.5 | 39.0 |
| BRC038_1_N_VThreadsAreTasks | 8 | 47.0 | 37.8 |
| BRC040_N_ConcurrentRead | 8 | 6.4 | 5.1 |
| BRC042_ForkJoinPool | 8 | 26.4 | 21.1 |
| BRC043_..._NoReducer | 8 | 26.0 | 20.8 |
| BRC044_..._SelfSplitting | 8 | 25.3 | 20.2 |
| BRC047_VirtualThreads | 8 | 42.8 | 34.2 |
| BRC048_VT_ChunkSize_10MB | 8 | 25.1 | 20.1 |
Performance counter stats for 'java -Xms2g -Xmx2g -cp target/classes/ org.rschwietzke.parallel.BRC001_Baseline -f data-1000m.txt -wc 0 -mc 1 -t 8':

         130,376.50 msec task-clock                       #    1.020 CPUs utilized
             18,943      context-switches                 #  145.295 /sec
              4,788      cpu-migrations                   #   36.724 /sec
            326,998      page-faults                      #    2.508 K/sec
👉  464,798,376,203      cycles                           #    3.565 GHz
     54,941,360,494      stalled-cycles-frontend          #   11.82% frontend cycles idle
👉2,380,905,128,702      instructions                     #    5.12  insn per cycle
                                                  #    0.02  stalled cycles per insn
    549,265,356,816      branches                         #    4.213 G/sec
      2,342,277,605      branch-misses                    #    0.43% of all branches

    ⏱127.773261850 seconds time elapsed

      124.145161000 seconds user
        5.642008000 seconds sys


Performance counter stats for 'java -Xms2g -Xmx2g -cp target/classes/ org.rschwietzke.parallel.BRC044_ForkJoinPool_SelfSplitting -f data-1000m.txt -wc 0 -mc 1 -t 8':

         195,689.07 msec task-clock                       #    7.527 CPUs utilized
             26,837      context-switches                 #  137.141 /sec
              4,385      cpu-migrations                   #   22.408 /sec
            333,597      page-faults                      #    1.705 K/sec
👉  694,817,257,247      cycles                           #    3.551 GHz
    124,646,585,103      stalled-cycles-frontend          #   17.94% frontend cycles idle
👉2,160,182,371,314      instructions                     #    3.11  insn per cycle
                                                  #    0.06  stalled cycles per insn
    495,875,578,633      branches                         #    2.534 G/sec
      2,251,135,482      branch-misses                    #    0.45% of all branches

    ⏱ 25.997951402 seconds time elapsed

      189.993214000 seconds user
        4.836329000 seconds sys
Let's Calculate
What Would Be Theoretically Possible?
Hardware
- AMD, 16-cores, 2.48 GHz
- Max IPC: About 6 (likely 7-8)
- Instructions per second max: 2.48 billion cycles x 6 IPC = 14.88 billion instruction per second
- Instructions per second likely: 2.48 billion cycles x 3 IPC = 7.4 billion instruction per second
Calculation
- Our code: 2.2 trillion instructions per run
- Max IPS: 147 s / 1 core
- Likely IPS: 295 s / 1 core
- Max IPS: 18.5 s / 8 cores
- Likely IPS: 36.9 s / 8 cores
Looking into CPU Time
Asking a Profiler
🔳🕒🕵️
CPU - Async-profiler to the rescue
Checking CPU time of BRC048_VT_ChunkSize_10MB
Allocations - Async-profiler to the rescue
Checking allocations of BRC048_VT_ChunkSize_10MB
Split is Slow
String::split does a lot of work
line.split()is slow- It allocates
String[] - It runs a block to see if it has to do regex matching
- It creates substrings
- Just a lot of code for a simple task
while ((line = r.readln()) != null) {
    var splitData = line.split(";");

    // first is the city
    var city = splitData[0];

    // second our double temperature
    var temperature = Double.parseDouble(splitData[1]);

    // get us our measurement record
    var measurement = new Temperatures(city, temperature);

    cities.merge(city, measurement, (t1, t2) -> t1.merge(t2));
}
while ((line = r.readln()) != null) {
    // split the line using indexOf
    final int semicolon = line.indexOf(';');
    final String city = line.substring(0, semicolon);
    final String temperatureString = line.substring(semicolon + 1);

    // second our double temperature
    var temperature = Double.parseDouble(temperatureString);

    // get us our measurement record
    var measurement = new Temperatures(city, temperature);

    cities.merge(city, measurement, (t1, t2) -> t1.merge(t2));
}
Results
| Test | C | Time | % | Cycles (B) | Instr (B) | Ctx Switches | CPU Migr | IPC |
|---|---|---|---|---|---|---|---|---|
| BRC001_Baseline | 1 | 124.5 | 100.0 | 459.5 | 2,351.5 | 18,946 | 3,870 | 5.12 |
| BRC010_ParallelAfterRead | 8 | 77.3 | 62.1 | 1,271.4 | 3,911.2 | 68,644 | 13,748 | 3.08 |
| BRC044..._SelfSplitting | 8 | 25.4 | 20.4 | 715.9 | 2,171.0 | 27,759 | 4,405 | 3.03 |
| BRC048_VT_ChunkSize_10MB | 8 | 25.4 | 20.4 | 738.6 | 2,188.7 | 27,899 | 4,467 | 2.96 |
| BRC060_44_SplitTune | 8 | 19.7 | 15.8 | 569.7 | 1,598.7 | 22,025 | 3,597 | 2.81 |
Double::parseDouble
String to double Parsing Is Heavy Too
Double::parseDoubleis heavy- It is made to support every edge case
- It supports different representations of numbers
- Handles overflows
- Handles leading zeros
- It is 224 lines long
- It allocates memory!
private static final int DIGITOFFSET = 48;

private static final double[] multipliers = {
    1, 1, 0.1, 0.01, 0.001, 0.000_1, 0.000_01, 0.000_001, 0.000_000_1, 0.000_000_01,
    0.000_000_001, 0.000_000_000_1, 0.000_000_000_01, 0.000_000_000_001, 0.000_000_000_000_1,
    0.000_000_000_000_01, 0.000_000_000_000_001, 0.000_000_000_000_000_1, 0.000_000_000_000_000_01};

public static double parseDouble(final String s)
{
    final int negative = s.charAt(0) == '-' ? 1 : 0;

    long value = 0;
    final int end = s.length();
    int decimalPos = end;

    for (int i = negative; i < end; i++)
    {
        final int d = s.charAt(i);
        if (d == '.')
        {
            decimalPos = i;
            continue;
        }
        final int v = d - DIGITOFFSET;
        value = value * 10 + v;
    }

    // set the sign
    value = negative == 1 ? -value : value;

    // adjust the decimal places
    return value * multipliers[end - decimalPos];
}
Results
| Test | C | Time | % | Cycles (B) | Instr (B) | Ctx Switches | CPU Migr | IPC |
|---|---|---|---|---|---|---|---|---|
| BRC001_Baseline | 1 | 124.5 | 100.0 | 459.5 | 2,351.5 | 18,946 | 3,870 | 5.12 |
| BRC010_ParallelAfterRead | 8 | 77.3 | 62.1 | 1,271.4 | 3,911.2 | 68,644 | 13,748 | 3.08 |
| BRC044..._SelfSplitting | 8 | 25.4 | 20.4 | 715.9 | 2,171.0 | 27,759 | 4,405 | 3.03 |
| BRC048_VT_ChunkSize_10MB | 8 | 25.4 | 20.4 | 738.6 | 2,188.7 | 27,899 | 4,467 | 2.96 |
| BRC060_44_SplitTune | 8 | 19.7 | 15.8 | 569.7 | 1,598.7 | 22,025 | 3,597 | 2.81 |
| BRC062_ParseDouble | 8 | 17.6 | 14.1 | 489.1 | 1,352.3 | 18,593 | 3,027 | 2.76 |
Get rid of Garbage
We Don't Need a Fresh String for Parsing
- We directly parse on the input line
- We skip one
Stringcreation
while ((line = r.readln()) != null)
{
    // split the line using indexOf
    final int semicolon = line.indexOf(';');
    final String city = line.substring(0, semicolon);
    final String temperatureString = line.substring(semicolon + 1);

    // second our double temperature
    var temperature = parseDouble(temperatureString);

    // get us our measurement record
    var measurement = new Temperatures(city, temperature);

    cities.merge(city, measurement, (t1, t2) -> t1.merge(t2));
}
while ((line = r.readln()) != null)
{
    // split the line using indexOf
    final int semicolon = line.indexOf(';');
    final String city = line.substring(0, semicolon);

    // second our double temperature
    final double temperature = parseDouble(line,
        semicolon + 1, line.length() - 1);

    // get us our measurement record
    var measurement = new Temperatures(city, temperature);

    cities.merge(city, measurement, (t1, t2) -> t1.merge(t2));
}
Results
| Test | C | Time | % | Cycles (B) | Instr (B) | Ctx Switches | CPU Migr | IPC |
|---|---|---|---|---|---|---|---|---|
| BRC001_Baseline | 1 | 124.5 | 100.0 | 459.5 | 2,351.5 | 18,946 | 3,870 | 5.12 |
| BRC010_ParallelAfterRead | 8 | 77.3 | 62.1 | 1,271.4 | 3,911.2 | 68,644 | 13,748 | 3.08 |
| BRC044..._SelfSplitting | 8 | 25.4 | 20.4 | 715.9 | 2,171.0 | 27,759 | 4,405 | 3.03 |
| BRC048_VT_ChunkSize_10MB | 8 | 25.4 | 20.4 | 738.6 | 2,188.7 | 27,899 | 4,467 | 2.96 |
| BRC060_44_SplitTune | 8 | 19.7 | 15.8 | 569.7 | 1,598.7 | 22,025 | 3,597 | 2.81 |
| BRC062_ParseDouble | 8 | 17.6 | 14.1 | 489.1 | 1,352.3 | 18,593 | 3,027 | 2.76 |
| BRC064_NoExtraString | 8 | 16.3 | 13.1 | 446.6 | 1,208.3 | 15,823 | 2,542 | 2.71 |
Simplify the Data
Who Needs double Anyway?
doubleuses more memory and is slower to process- Delay
doublehandling till we really need adoubleresult - We know the data format, so we can ignore the "
."
private static final int DIGITOFFSET = 48;

/**
    * Parses a double but ends up with an int, only because we know
    * the format of the results -99.9 to 99.9
    */
public static int parseInteger(final String s, final int offset, final int end)
{
    final int negative = s.charAt(offset) == '-' ? offset + 1 : offset;

    int value = 0;

    for (int i = negative; i < end; i++)
    {
        final int d = s.charAt(i);
        if (d == '.')
        {
            continue;
        }
        final int v = d - DIGITOFFSET;
        value = value * 10 + v;
    }

    value = negative != offset ? -value : value;
    return value;
}
Results
| Test | C | Time | % | Cycles (B) | Instr (B) | Ctx Switches | CPU Migr | IPC |
|---|---|---|---|---|---|---|---|---|
| BRC001_Baseline | 1 | 124.5 | 100.0 | 459.5 | 2,351.5 | 18,946 | 3,870 | 5.12 |
| BRC010_ParallelAfterRead | 8 | 77.3 | 62.1 | 1,271.4 | 3,911.2 | 68,644 | 13,748 | 3.08 |
| BRC044..._SelfSplitting | 8 | 25.4 | 20.4 | 715.9 | 2,171.0 | 27,759 | 4,405 | 3.03 |
| BRC048_VT_ChunkSize_10MB | 8 | 25.4 | 20.4 | 738.6 | 2,188.7 | 27,899 | 4,467 | 2.96 |
| BRC060_44_SplitTune | 8 | 19.7 | 15.8 | 569.7 | 1,598.7 | 22,025 | 3,597 | 2.81 |
| BRC062_ParseDouble | 8 | 17.6 | 14.1 | 489.1 | 1,352.3 | 18,593 | 3,027 | 2.76 |
| BRC064_NoExtraString | 8 | 16.3 | 13.1 | 446.6 | 1,208.3 | 15,823 | 2,542 | 2.71 |
| BRC066_Integer | 8 | 14.6 | 11.7 | 408.6 | 1,110.1 | 14,682 | 2,512 | 2.72 |
Making it Nicer for the Hardware
Loops Incur Penalties
- CPUs don't like to go back
- We know the data format
- Sequential parsing instead of looping
private static final int DIGITOFFSET = 48;

/**
    * Parses a double but ends up with an int, only because we know
    * the format of the results -99.9 to 99.9
    *
    * Best case, two branches
    * Worst case, two branches
    */
public static int parseInteger(final String s, int offset, final int end)
{
    int l = end - offset;
    var p0 = s.charAt(end - 1);
    var p2 = s.charAt(end - 3) * 10;
    var value = p2 + p0 - (DIGITOFFSET * 10 + DIGITOFFSET);

    final char firstChar = s.charAt(offset);
    if (firstChar == '-') {
        if (l == 5) {
            // -99.9
            var p3 = s.charAt(end - 4) * 100;
            value = p3 + value - (DIGITOFFSET * 100);
        }
        else {
            // -9.9
        }
        return -value;
    }
    else {
        if (l == 4) {
            // 99.9
            // we can use firstChar directly as we know its not '-'
            var p3 = firstChar * 100;
            value = p3 + value - (DIGITOFFSET * 100);
        }
        else {
            // 9.9
        }
        return value;
    }
}
Results
| Test | C | Time | % | Cycles (B) | Instr (B) | Ctx Switches | CPU Migr | IPC |
|---|---|---|---|---|---|---|---|---|
| BRC001_Baseline | 1 | 124.5 | 100.0 | 459.5 | 2,351.5 | 18,946 | 3,870 | 5.12 |
| BRC010_ParallelAfterRead | 8 | 77.3 | 62.1 | 1,271.4 | 3,911.2 | 68,644 | 13,748 | 3.08 |
| BRC044..._SelfSplitting | 8 | 25.4 | 20.4 | 715.9 | 2,171.0 | 27,759 | 4,405 | 3.03 |
| BRC048_VT_ChunkSize_10MB | 8 | 25.4 | 20.4 | 738.6 | 2,188.7 | 27,899 | 4,467 | 2.96 |
| BRC060_44_SplitTune | 8 | 19.7 | 15.8 | 569.7 | 1,598.7 | 22,025 | 3,597 | 2.81 |
| BRC062_ParseDouble | 8 | 17.6 | 14.1 | 489.1 | 1,352.3 | 18,593 | 3,027 | 2.76 |
| BRC064_NoExtraString | 8 | 16.3 | 13.1 | 446.6 | 1,208.3 | 15,823 | 2,542 | 2.71 |
| BRC066_Integer | 8 | 14.6 | 11.7 | 408.6 | 1,110.1 | 14,682 | 2,512 | 2.72 |
| BRC068_ParsingWithoutALoop | 8 | 13.6 | 11.0 | 374.3 | 1,031.1 | 14,239 | 2,399 | 2.75 |
The Best Memory Is No Memory
Immutability Is Good But Mutations Are Better
- Avoid creating intermediate objects
- Mutate our counters
- Update memory, don't allocate and free it like mad
/**
    * Holds our temperature data without the station, because the
    * map already knows that
    */
private static class Temperatures
{
    private int min;
    private int max;
    private long total;
    private long count;

    public Temperatures(final int temperature)
    {
        this.min = temperature;
        this.max = temperature;
        this.total = temperature;
        this.count = 1;
    }

    public Temperatures merge(final int temperature)
    {
        this.min = Math.min(this.min, temperature);
        this.max = Math.max(this.max, temperature);
        this.total += temperature;
        this.count += 1;
        return this;
    }
    ...
}
Results
| Test | C | Time | % | Cycles (B) | Instr (B) | Ctx Switches | CPU Migr | IPC |
|---|---|---|---|---|---|---|---|---|
| BRC001_Baseline | 1 | 124.5 | 100.0 | 459.5 | 2,351.5 | 18,946 | 3,870 | 5.12 |
| BRC010_ParallelAfterRead | 8 | 77.3 | 62.1 | 1,271.4 | 3,911.2 | 68,644 | 13,748 | 3.08 |
| BRC044..._SelfSplitting | 8 | 25.4 | 20.4 | 715.9 | 2,171.0 | 27,759 | 4,405 | 3.03 |
| BRC048_VT_ChunkSize_10MB | 8 | 25.4 | 20.4 | 738.6 | 2,188.7 | 27,899 | 4,467 | 2.96 |
| BRC060_44_SplitTune | 8 | 19.7 | 15.8 | 569.7 | 1,598.7 | 22,025 | 3,597 | 2.81 |
| BRC062_ParseDouble | 8 | 17.6 | 14.1 | 489.1 | 1,352.3 | 18,593 | 3,027 | 2.76 |
| BRC064_NoExtraString | 8 | 16.3 | 13.1 | 446.6 | 1,208.3 | 15,823 | 2,542 | 2.71 |
| BRC066_Integer | 8 | 14.6 | 11.7 | 408.6 | 1,110.1 | 14,682 | 2,512 | 2.72 |
| BRC068_ParsingWithoutALoop | 8 | 13.6 | 11.0 | 374.3 | 1,031.1 | 14,239 | 2,399 | 2.75 |
| BRC070_Mutate | 8 | 12.9 | 10.4 | 351.1 | 989.4 | 10,176 | 1,861 | 2.82 |
| BRC072_Mutate_BetterReader | 8 | 12.9 | 10.3 | 350.2 | 1,016.1 | 10,007 | 1,935 | 2.90 |
Why Strings?
Reduce The Churn Even More
Stringobjects are immutableStringobjects need a conversion frombytedata- Why not stay
byteuntil we need aString? -,;and\n, and0-9are the same in UTF-8- Reduce also with
byteand notString - Fold the key into the data object
private static class City {
    private int min;
    private int max;
    private long total;
    private long count;
    private final byte[] name;
    private final int hashCode;

    public City(byte[] bytes, int semicolon, int temperature, int hashCode) {
        this.name = Arrays.copyOfRange(bytes, 0, semicolon);
        this.max = temperature;
        this.min = temperature;
        this.total = temperature;
        this.count = 1;
        this.hashCode = hashCode;
    }

    public City update(int temperature) {
        this.min = Math.min(this.min, temperature);
        this.max = Math.max(this.max, temperature);
        count++;
        this.total += temperature;

        return this;
    }

    public City merge(final City city) {
        this.min = Math.min(this.min, city.min);
        this.max = Math.max(this.max, city.max);
        this.total += city.total;
        this.count += city.count;

        return this;
    }
...
}
Results
| Test | C | Time | % | Cycles (B) | Instr (B) | Ctx Switches | CPU Migr | IPC |
|---|---|---|---|---|---|---|---|---|
| BRC001_Baseline | 1 | 124.5 | 100.0 | 459.5 | 2,351.5 | 18,946 | 3,870 | 5.12 |
| BRC010_ParallelAfterRead | 8 | 77.3 | 62.1 | 1,271.4 | 3,911.2 | 68,644 | 13,748 | 3.08 |
| BRC044..._SelfSplitting | 8 | 25.4 | 20.4 | 715.9 | 2,171.0 | 27,759 | 4,405 | 3.03 |
| BRC048_VT_ChunkSize_10MB | 8 | 25.4 | 20.4 | 738.6 | 2,188.7 | 27,899 | 4,467 | 2.96 |
| BRC060_44_SplitTune | 8 | 19.7 | 15.8 | 569.7 | 1,598.7 | 22,025 | 3,597 | 2.81 |
| BRC062_ParseDouble | 8 | 17.6 | 14.1 | 489.1 | 1,352.3 | 18,593 | 3,027 | 2.76 |
| BRC064_NoExtraString | 8 | 16.3 | 13.1 | 446.6 | 1,208.3 | 15,823 | 2,542 | 2.71 |
| BRC066_Integer | 8 | 14.6 | 11.7 | 408.6 | 1,110.1 | 14,682 | 2,512 | 2.72 |
| BRC068_ParsingWithoutALoop | 8 | 13.6 | 11.0 | 374.3 | 1,031.1 | 14,239 | 2,399 | 2.75 |
| BRC070_Mutate | 8 | 12.9 | 10.4 | 351.1 | 989.4 | 10,176 | 1,861 | 2.82 |
| BRC072_Mutate_BetterReader | 8 | 12.9 | 10.3 | 350.2 | 1,016.1 | 10,007 | 1,935 | 2.90 |
| BRC075_Bytes_ConcurrentRead | 8 | 6.3 | 5.1 | 180.6 | 502.1 | 1,159 | 131 | 2.78 |
| BRC075_Bytes_ConcurrentRead | 16 | 3.5 | 2.8 | 89.6 | 501.2 | 1,309 | 91 | 2.81 |
| BRC076_Bytes_ForkJoin_Full | 8 | 11.4 | 9.1 | 324.8 | 851.1 | 8,055 | 1,621 | 2.62 |
| BRC076_Bytes_ForkJoin_Full | 16 | 6.4 | 5.4 | 323.6 | 860.8 | 14,495 | 588 | 2.66 |
Reduce ForkJoinPool Logic
Don't split deep
- Avoid deep tasks
- Just fork off as desired right on level 1
- Disadvantage: We might wait for the last task before we join things together
protected Map<City, City> compute() {
    // split only when we should
    if (taskCount > 1)
    {
        final List<Mapper> tasks = new ArrayList<>(taskCount);

        final long size = this.to - this.from;
        final long chunkSize = size / taskCount;

        long from = -chunkSize;
        long to = 0;
        while (to < size) {
            from += chunkSize;
            to = from + chunkSize;

            // when close to the end, make one chunk larger
            // than really small... otherwise we lose data
            to = (size - to) < chunkSize ? size : to;

            tasks.add(new Mapper(filePath, from, to, 1));
        }
        ForkJoinTask.invokeAll(tasks);

        // reduce result
        final Map<City, City> cities = new HashMap<>();

        for (var t : tasks) {
            try {
                final var result = t.get();

                result.forEach((k, v) ->
                    cities.compute(k, (_, v2) -> v2 == null ? v : v2.merge(v)));
            }
            catch (InterruptedException e) {
                throw new RuntimeException(e);
            }
            catch (ExecutionException e) {
                throw new RuntimeException(e);
            }
        }

        return cities;
    }
    else {
        return map();
    }
}
Results
| Test | C | Time | % | Cycles (B) | Instr (B) | Ctx Switches | CPU Migr | IPC |
|---|---|---|---|---|---|---|---|---|
| BRC001_Baseline | 1 | 124.5 | 100.0 | 459.5 | 2,351.5 | 18,946 | 3,870 | 5.12 |
| BRC010_ParallelAfterRead | 8 | 77.3 | 62.1 | 1,271.4 | 3,911.2 | 68,644 | 13,748 | 3.08 |
| BRC044..._SelfSplitting | 8 | 25.4 | 20.4 | 715.9 | 2,171.0 | 27,759 | 4,405 | 3.03 |
| BRC048_VT_ChunkSize_10MB | 8 | 25.4 | 20.4 | 738.6 | 2,188.7 | 27,899 | 4,467 | 2.96 |
| BRC060_44_SplitTune | 8 | 19.7 | 15.8 | 569.7 | 1,598.7 | 22,025 | 3,597 | 2.81 |
| BRC062_ParseDouble | 8 | 17.6 | 14.1 | 489.1 | 1,352.3 | 18,593 | 3,027 | 2.76 |
| BRC064_NoExtraString | 8 | 16.3 | 13.1 | 446.6 | 1,208.3 | 15,823 | 2,542 | 2.71 |
| BRC066_Integer | 8 | 14.6 | 11.7 | 408.6 | 1,110.1 | 14,682 | 2,512 | 2.72 |
| BRC068_ParsingWithoutALoop | 8 | 13.6 | 11.0 | 374.3 | 1,031.1 | 14,239 | 2,399 | 2.75 |
| BRC070_Mutate | 8 | 12.9 | 10.4 | 351.1 | 989.4 | 10,176 | 1,861 | 2.82 |
| BRC072_Mutate_BetterReader | 8 | 12.9 | 10.3 | 350.2 | 1,016.1 | 10,007 | 1,935 | 2.90 |
| BRC075_Bytes_ConcurrentRead | 8 | 6.3 | 5.1 | 180.6 | 502.1 | 1,159 | 131 | 2.78 |
| BRC075_Bytes_ConcurrentRead | 16 | 3.5 | 2.8 | 89.6 | 501.2 | 1,309 | 91 | 2.81 |
| BRC076_Bytes_ForkJoin_Full | 8 | 11.4 | 9.1 | 324.8 | 851.1 | 8,055 | 1,621 | 2.62 |
| BRC076_Bytes_ForkJoin_Full | 16 | 6.4 | 5.4 | 323.6 | 860.8 | 14,495 | 588 | 2.66 |
| BRC077_Bytes_ForkJoin_1Level | 8 | 11.0 | 8.8 | 319.1 | 851.6 | 7,470 | 1,596 | 2.67 |
| BRC077_Bytes_ForkJoin_1Level | 16 | 6.2 | 5.2 | 321.7 | 865.0 | 13,180 | 353 | 2.69 |
# Before Tuning
Performance counter stats for 'java -Xms2g -Xmx2g org.rschwietzke.parallel.BRC044_ForkJoinPool_SelfSplitting -f data-1000m.txt -wc 0 -mc 1 -t 8':

         195,689.07 msec task-clock                       #    7.527 CPUs utilized
             26,837      context-switches                 #  137.141 /sec
              4,385      cpu-migrations                   #   22.408 /sec
            333,597      page-faults                      #    1.705 K/sec
👉  694,817,257,247      cycles                           #    3.551 GHz
    124,646,585,103      stalled-cycles-frontend          #   17.94% frontend cycles idle
👉2,160,182,371,314      instructions                     #    3.11  insn per cycle
                                                  #    0.06  stalled cycles per insn
    495,875,578,633      branches                         #    2.534 G/sec
      2,251,135,482      branch-misses                    #    0.45% of all branches

       25.997951402 seconds time elapsed

      189.993214000 seconds user
        4.836329000 seconds sys

# Basic Tuning Applied
Performance counter stats for 'java -Xms2g -Xmx2g org.rschwietzke.parallel.BRC077_Bytes_ForkJoin_1Level -f data-1000m.txt -wc 0 -mc 1 -t 8':

          87,243.92 msec task-clock                       #    7.665 CPUs utilized
              7,340      context-switches                 #   84.132 /sec
              1,535      cpu-migrations                   #   17.594 /sec
            325,138      page-faults                      #    3.727 K/sec
👉  311,042,959,884      cycles                           #    3.565 GHz
     46,899,550,857      stalled-cycles-frontend          #   15.08% frontend cycles idle
👉  841,246,054,158      instructions                     #    2.70  insn per cycle
                                                  #    0.06  stalled cycles per insn
    149,906,105,350      branches                         #    1.718 G/sec
      1,826,627,665      branch-misses                    #    1.22% of all branches

       11.381797466 seconds time elapsed

       83.807472000 seconds user
        3.292472000 seconds sys
More Results
| Test | C | Time | % | Cycles (B) | Instr (B) | Ctx Switches | CPU Migr | IPC |
|---|---|---|---|---|---|---|---|---|
| BRC001_Baseline | 1 | 124.5 | 100.0 | 459.5 | 2,351.5 | 18,946 | 3,870 | 5.12 |
| BRC060_44_SplitTune | 8 | 19.7 | 15.8 | 569.7 | 1,598.7 | 22,025 | 3,597 | 2.81 |
| BRC062_ParseDouble | 8 | 17.6 | 14.1 | 489.1 | 1,352.3 | 18,593 | 3,027 | 2.76 |
| BRC064_NoExtraString | 8 | 16.3 | 13.1 | 446.6 | 1,208.3 | 15,823 | 2,542 | 2.71 |
| BRC066_Integer | 8 | 14.6 | 11.7 | 408.6 | 1,110.1 | 14,682 | 2,512 | 2.72 |
| BRC068_ParsingWithoutALoop | 8 | 13.6 | 11.0 | 374.3 | 1,031.1 | 14,239 | 2,399 | 2.75 |
| BRC070_Mutate | 8 | 12.9 | 10.4 | 351.1 | 989.4 | 10,176 | 1,861 | 2.82 |
| BRC076_Bytes_ForkJoin_Full | 8 | 11.4 | 9.1 | 324.8 | 851.1 | 8,055 | 1,621 | 2.62 |
| BRC076_Bytes_ForkJoin_Full | 16 | 6.4 | 5.4 | 323.6 | 860.8 | 14,495 | 588 | 2.66 |
| BRC077_Bytes_..._1Level | 8 | 11.0 | 8.8 | 319.1 | 851.6 | 7,470 | 1,596 | 2.67 |
| BRC077_Bytes_..._1Level | 16 | 6.2 | 5.2 | 321.7 | 865.0 | 13,180 | 353 | 2.69 |
| BRC080_Set | 8 | 7.8 | 6.3 | 220.0 | 640.6 | 714 | 46 | 2.91 |
| BRC080_Set | 16 | 4.2 | 3.4 | 225.6 | 647.2 | 1,577 | 46 | 2.87 |
-Xms5m -Xmx5m -XX:+UseEpsilonGC
The first 80% are not too hard.
Change one thing at a time and measure.